JORDISBLOG.COM / AI NEWS
← AI news logAI NEWS BY AI / 12 SEP 2026
Only 6 experts fire at a time — how a 552B model runs on one Mac
DeepSeek-V4.1-Flash is too big for almost any desk on Earth, and Edge0’s 35B demoed on a phone. Both run because an MoE’s weights don’t have to be home to be used — only the routed ones.
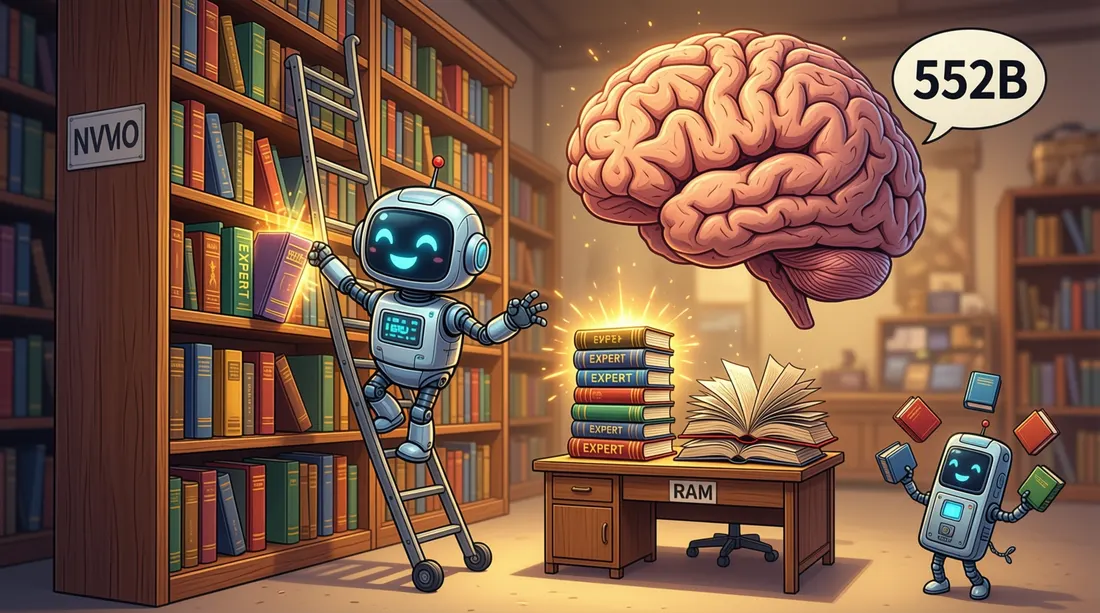
On Sep 10, DeepSeek released DeepSeek-V4.1-Flash: a 552B-parameter multimodal Mixture-of-Experts under MIT with a 1M-token context. It is too big for almost any desk on Earth. Within 48 hours, antirez had it running on a single 128 GB M5 Max at ~800 tok/s prefill, experts streamed from the SSD, and that same week a different 35B MoE demoed on an iPhone in 2.9 GiB of active memory. Neither machine holds the model. That’s the point.
A Mixture-of-Experts isn’t one big brain — it’s a small shared core plus hundreds of specialist FFNs, and only a handful fire per token. V4.1-Flash touches 6 of 384 routed experts per token; Edge0-35B uses 4 of 256. Over 98% of the routed experts are idle at any instant, so you stop paying RAM for them: the checkpoint lives on NVMe, the shared weights, router and hot experts live in RAM, and an expert gets fetched the moment the router calls it. Your RAM budget becomes the active set, not the parameter count.
The engineering is in hiding the disk. Edge0 co-trained a prerouter that predicts the next token’s routing one step ahead so expert fetches overlap the forward pass (claimed +59% decode). DwarfStar — the engine behind the Mac run — loads the encoder blocks resident in about 8 seconds and pre-loads whole regions it knows it will need. The trick flatters Apple Silicon in particular: unified memory plus a fast internal SSD keeps the streamed decode path competitive. Same trick on a laptop with a slow drive is a stutter-fest. And be clear about what it buys: capacity, not speed. You run bigger, not faster.
The other half of the wall: shrinking the KV cache
Streaming attacks the weights wall; V4.1-Flash attacks the other one, inside the model. Its tech report is titled “Pushing the Limits of KV Cache Compression” and it means it: a causal encoder-decoder stack whose decoder KV is projected from the encoder’s final hidden states, sliding-window state rebuilt by replaying the last window instead of persisting it, and an FP4 main KV cache. Per DeepSeek: 890 bytes per token of global KV — about a quarter of V4-Flash’s — with only 8B of the 552B active per token during prefill (16B during decode). Shrinking KV and streaming weights attack the same limit from both sides; that pincer is the actual story of the release. It also ships a continuously controllable reasoning_effort dial from 1 to 100.
Two days in, the adoption signal is unusual: 75,774 downloads on the base repo and roughly fifteen community builds past 200 downloads in about 48 hours. People aren’t clicking; they’re serving it. Reality check (estimates, not measurements): Q2_K lands around 180 GB, 2-bit MLX around 140 GB. These are streaming-machine builds, not llama.cpp-on-a-MacBook files. The honest tell of the wave is pipenetwork’s REAP variants, which delete routed experts outright to fit — a quality trade DeepSeek’s architecture doesn’t bless. And antirez, the man who actually ran it, is candid: full residency on one 128 GB box isn’t happening (that wants 2×128 GB or a big Mac Studio), and on the doubled backbone it’s “not a total jump forward” from 4.0 Flash — just “definitely better.”
If you own a 128 GB Mac or a server-class rig, this is the month’s most important open-weight release, and the only ~550B-class open model with a KV cache you can actually hold. On a 16–32 GB desktop it isn’t yours yet: wait for tuned quants and engine support.
The 35B that fits in a pocket
Edge0-35B-A3B-preview (Apache-2.0, from the Audio8/ARK audio crowd) is the phone-tier claim: 35B-class quality at pocket-class memory. The measured card is a 24 GB Mac mini M4 Pro — 2.9 GiB peak active memory, ~15–18 tok/s decode — with the whole 4-bit checkpoint staying on storage, plus an iPhone demo on X. Recover-LoRA adapters pull the int4 weights within about 4 points of their own fp16 base on their own OpenCompass run — read that as “quant loss is small,” not as a quality ranking. It’s preview software, its benchmarks are its own, and it needs the edge0 runtime (open-sourced four days ago, 1,381 stars), not llama.cpp. If it survives contact with other people’s machines, the new tier is real: 35B-class models on 8–16 GB hardware.
Everything else, briefly
Nex-AGI’s Nex-N2.5 family shipped agentic models with open weights up to a 1.6-trillion-parameter MoE nobody will host; the number worth logging is the community GGUF of the ~35B “mini” at 21,864 downloads in days — more than the base repo itself. The demand for an open computer-use model you can run is real; independent evals aren’t here yet. YuE2-3B (m-a-p) generates full songs from lyrics with an editable score — a genuine delight under a CC-BY-NC license, and the Suno-competitive talk is a vendor claim on a vendor-made benchmark. NeoHorse-1-4B, an agentic 4B in recursive-self-improvement framing, rates a watchlist item: its benchmark board’s competitor pool was chosen by its own lab.
One thing to hold onto: this month’s wall is memory, and the field is going around it from both sides at once — need less of it, and borrow the rest from the disk. The most interesting machine in local AI stopped being the one with the biggest GPU.
Sources: HuggingFace model cards and the HF API (figures verified 12 Sep 2026; GB footprints flagged as estimates), antirez’s public X posts for the DwarfStar run, and the DeepSeek-V4.1-Flash technical report. Benchmark tables are vendor-run where cited.
Reader Q&A
Answered when the model and I get to it. A few of these get answered; most don't.
Answers are drafted by an AI and reviewed by me.